Shihao Wang
About Me
I am a Ph.D. candidate in the Department of Computing at The Hong Kong Polytechnic University, advised by Prof. Lei Zhang (IEEE Fellow), and a research intern at NVIDIA Research. My research asks one question: how should a model represent the physical world efficiently?
A robot or vehicle cannot afford dense pixels, every frame, and coordinates spelled out token by token. It needs a compact state that keeps what matters for acting: what is there, where it is, and how it changes.
Sparse in space
StreamPETR carries a 3D scene through time with a few hundred object queries instead of a dense BEV grid, matching LiDAR-based detectors at a fraction of the cost.
Parallel in output
LocateAnything decodes boxes in parallel rather than token by token, across images, robotics, GUIs, and documents; LocateAnything3D extends this to 3D.
Selective in time
VideoITG keeps only the frames an instruction needs.
These representations run inside Cosmos 3, Isaac GR00T N1.6, Vesta, Nemotron 3 Nano Omni and Nemotron 3.5 Super, as well as Autoware and TensorRT on DRIVE. Next, I aim to unify objects, geometry, and time into a single compact world state that VLA policies can plan on and check against reality over long horizons.
source: Google Scholar, Oct 2026
News
- 2026.10 Released OmniCompass, a holistic benchmark for omni-modal video grounding and understanding.
- 2026 LocateAnything accepted to ECCV 2026; DepthMaster accepted to NeurIPS 2026.
- 2026.06 Vesta and Cosmos 3 are out, with grounding, spatial-understanding and robotics data from my work.
- 2026.05 LocateAnything is the Hugging Face #1 Paper of the Day, with 1M+ downloads in its first month.
- 2026.04 Nemotron 3 Nano Omni released, with visual grounding and GUI understanding from LocateAnything.
- 2026 Four papers accepted to CVPR 2026: VideoITG (Highlight), PhyCritic, LocateAnything3D and VOSR.
- 2026.02 Joined NVIDIA Research (Singapore) as a research intern on Physical AI / Embodied Intelligence.
- 2025.09 Two papers accepted to NeurIPS 2025 (Eagle 2.5, DP2O-SR).
- 2025.06 Hydra-NeXt and InsViE-1M accepted to ICCV 2025; contributed to the release of GR00T N1.5.
- 2025.02 OmniDrive accepted to CVPR 2025.
- 2024.06 1st place (of 143 teams) & Innovation Award in End-to-End Driving at Scale, and 2nd place in Driving with Language, CVPR 2024 Autonomous Driving Grand Challenge.
- 2023.07 StreamPETR accepted to ICCV 2023.
Selected Work & Impact
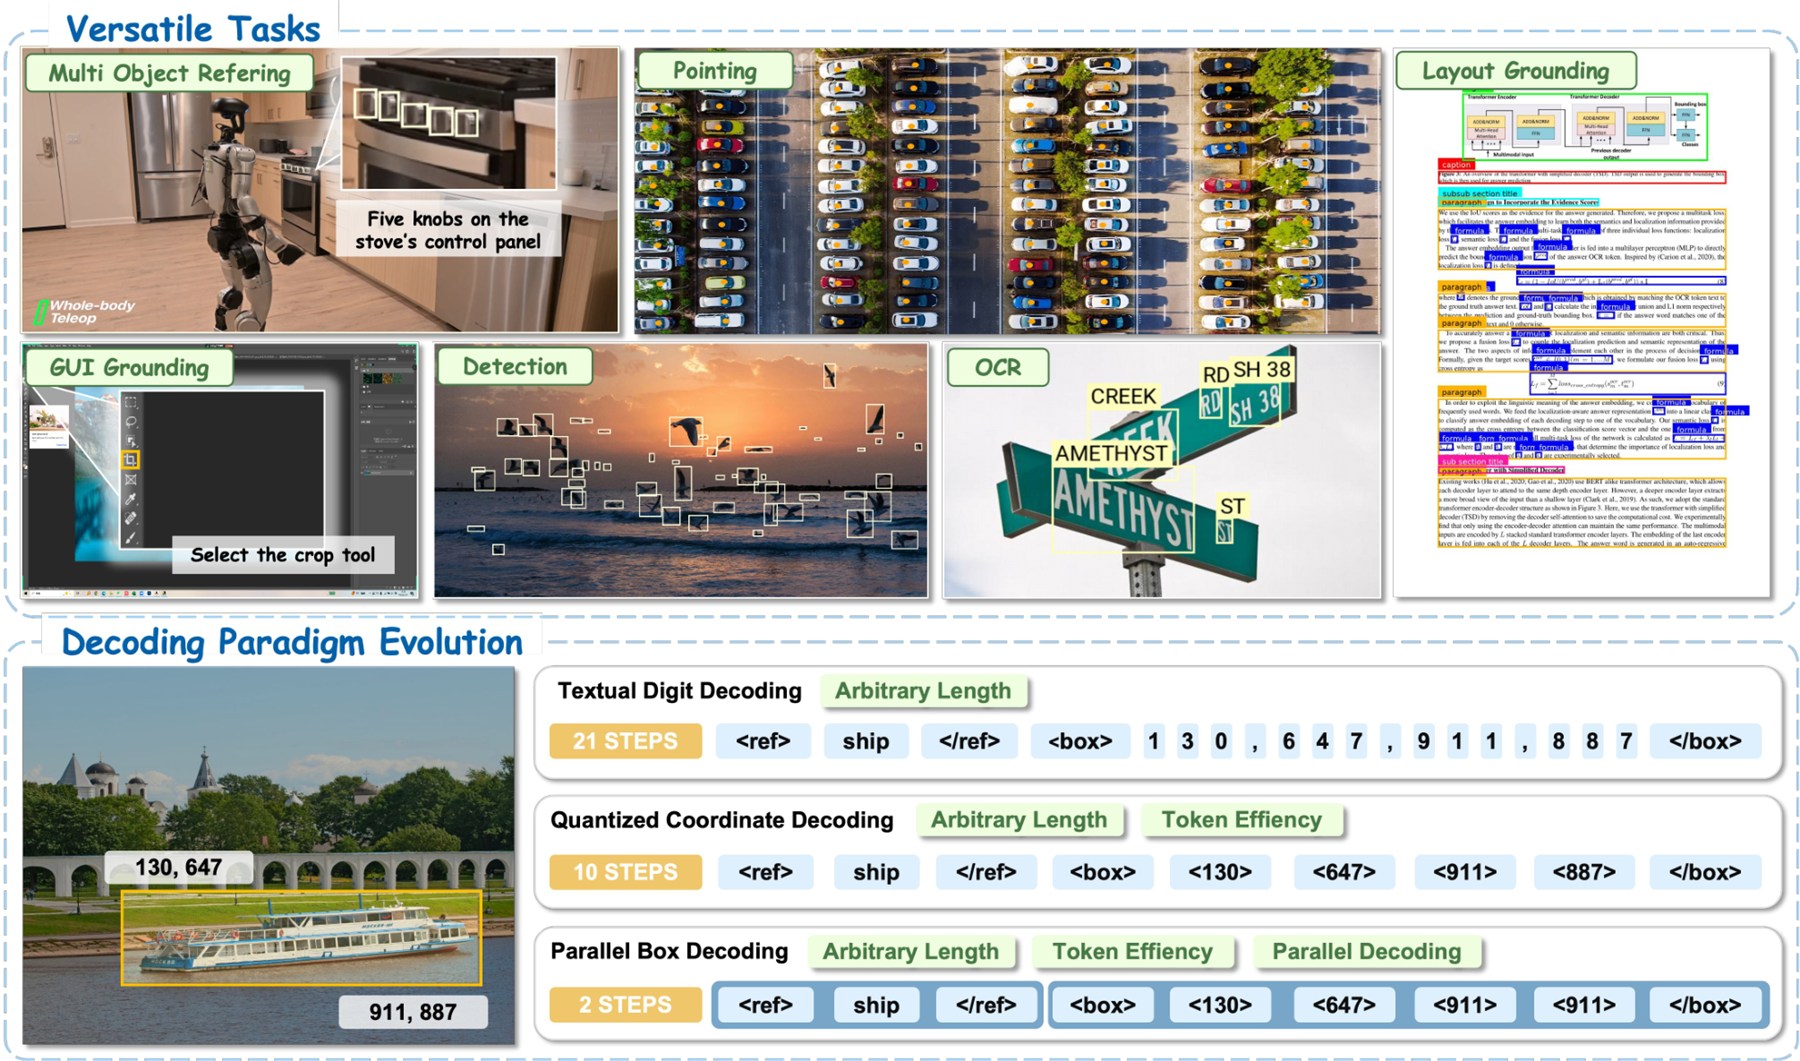
LocateAnything: Fast and High-Quality Vision-Language Grounding with Parallel Box Decoding
A unified grounding model across natural images, robotics, driving, GUIs, and documents. Parallel Box Decoding decodes each box or point as a single unit (~2.5× faster than the strongest unified model), trained on LocateAnything-Data (12M images, 138M queries).
1M+ downloads in one month. Powers grounding in Nemotron 3 Nano Omni and Vesta, and forms the majority of the 2D grounding SFT corpus of Cosmos 3. Community ports: WebGPU, C++/ggml (LocalAI), GGUF, ComfyUI.
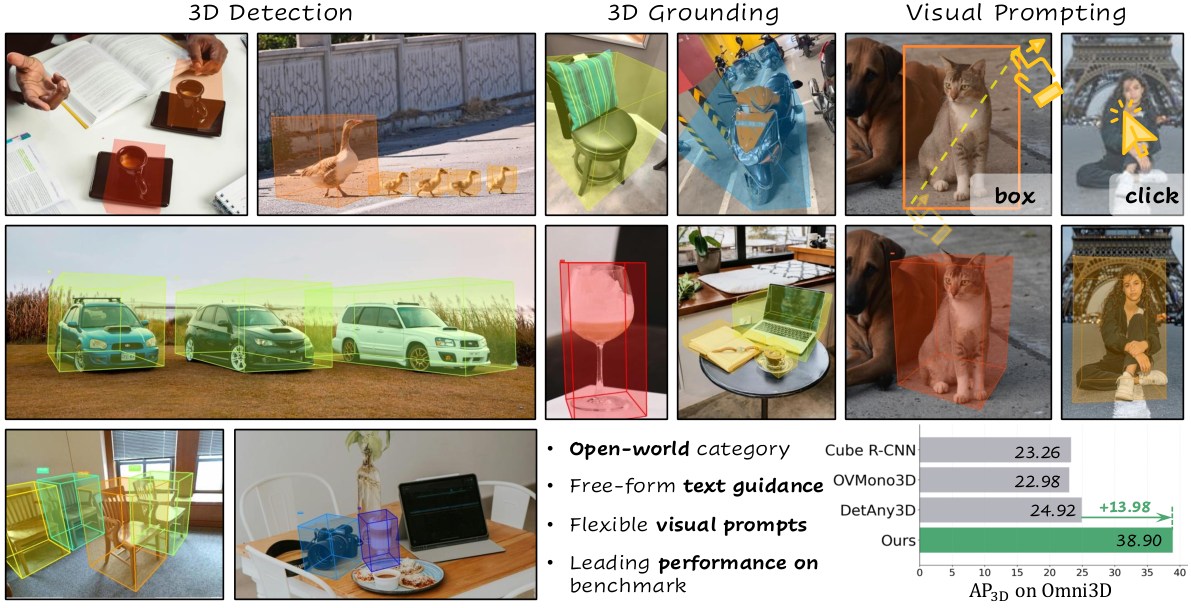
LocateAnything3D: Vision-Language 3D Detection with Chain-of-Sight
Extends VLM-native grounding to 3D with Chain-of-Sight reasoning over distance, size, and pose. SOTA on Omni3D with strong outdoor generalization.
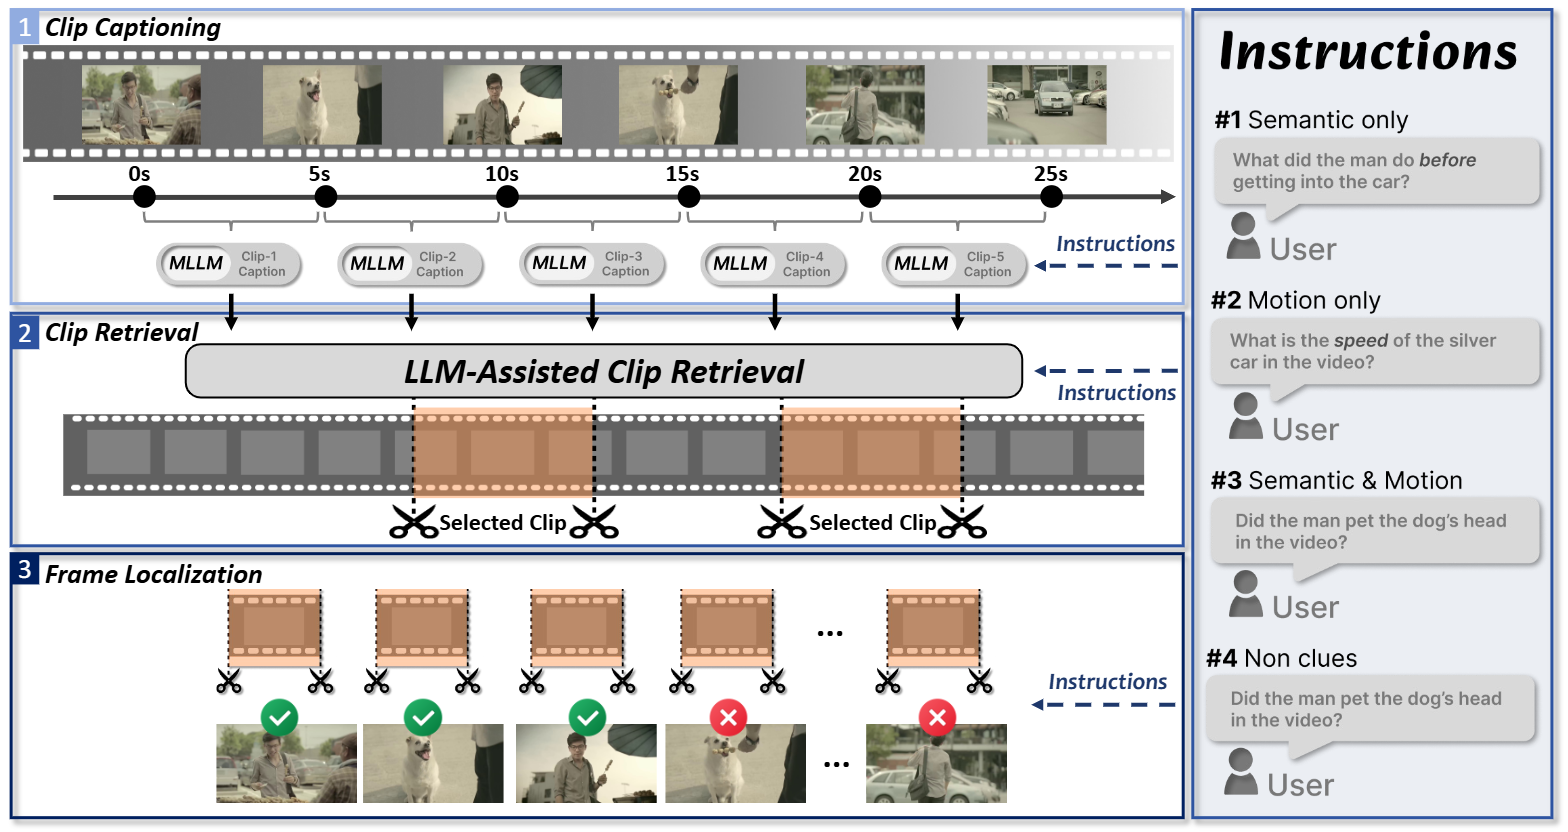
VideoITG: Multimodal Video Understanding with Instructed Temporal Grounding
Instruction-conditioned frame selection for Video-LLMs, supervised by VidThinker, an agentic annotation workflow. SOTA on VideoMME, MLVU, and LongVideoBench.
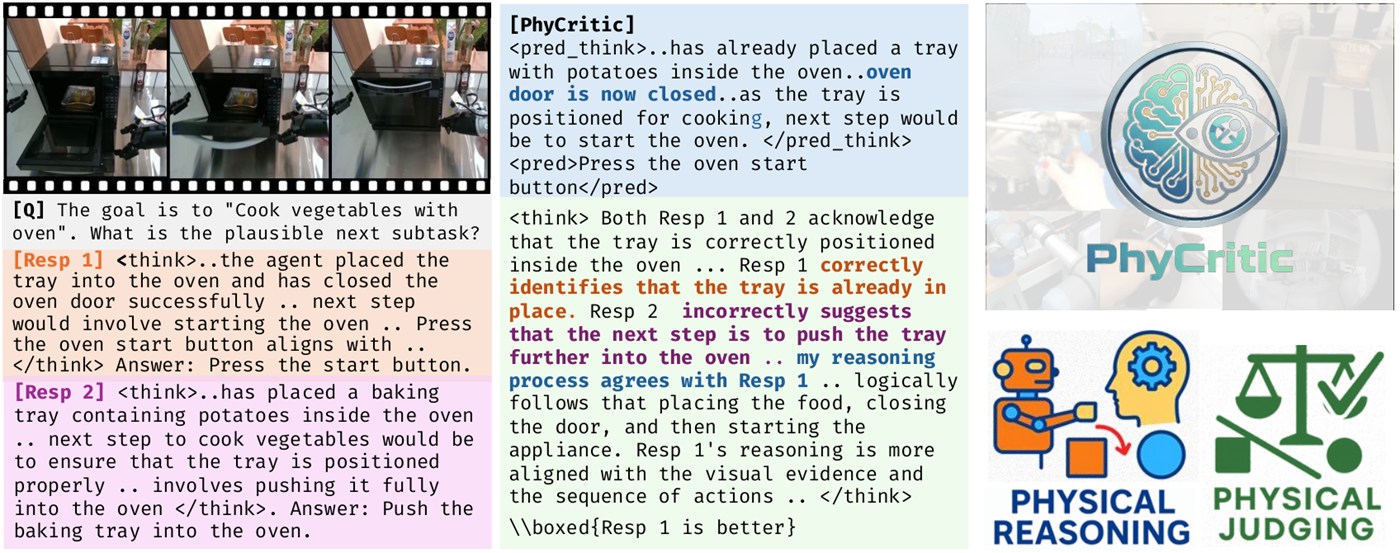
PhyCritic: Multimodal Critic Models for Physical AI
Critic models trained with a two-stage RLVR pipeline, where the critic forms its own prediction before judging candidates, providing reward and verification signals for Physical AI.
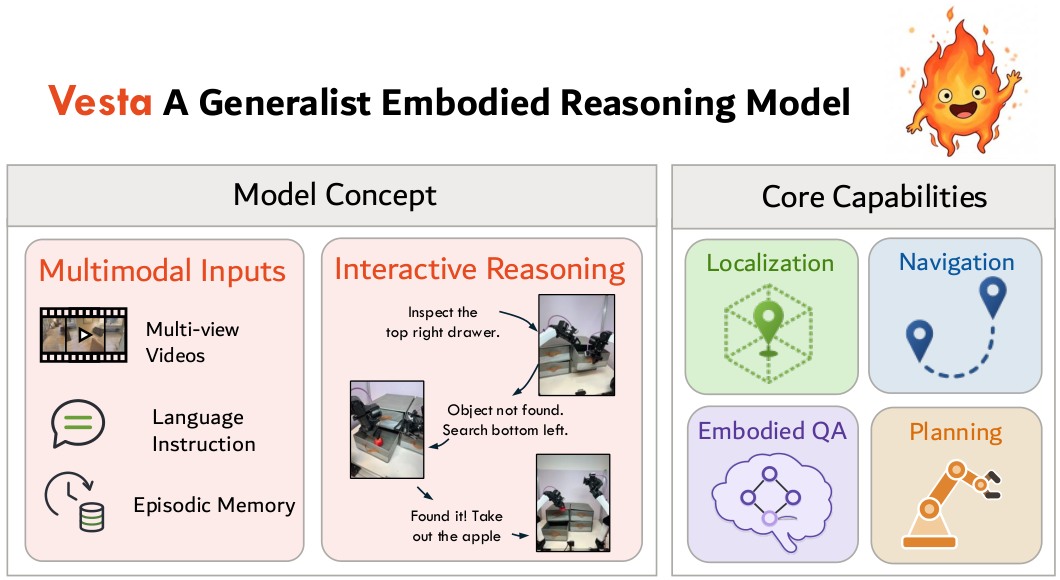
Vesta: A Generalist Embodied Reasoning Model
Led the data engine for perception and spatial understanding of this generalist embodied reasoning model, which beats individual SOTA baselines by >20% on average.
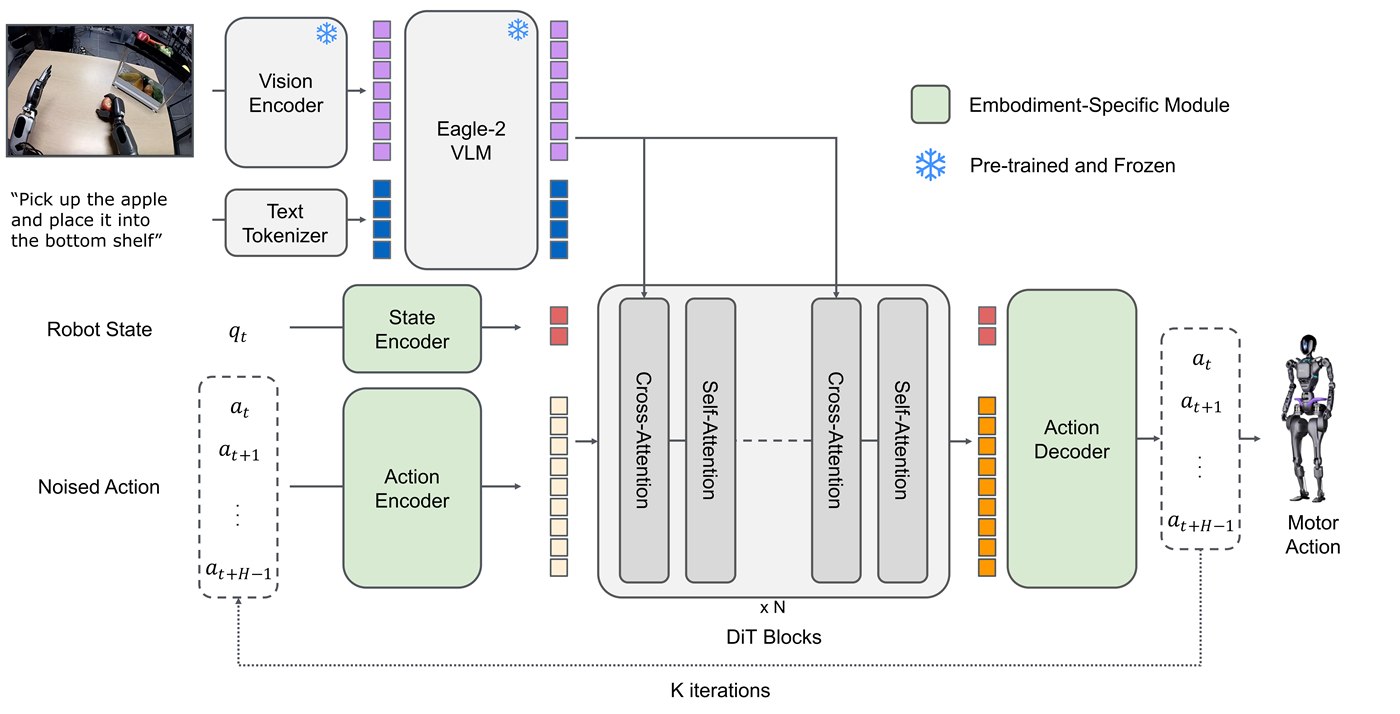
Isaac GR00T N1.5 / N1.6
Built the vision-language base model on Eagle 2.5, introduced native any-resolution input to preserve fine spatial detail for robot policies, and owned the large-scale spatial-understanding data.
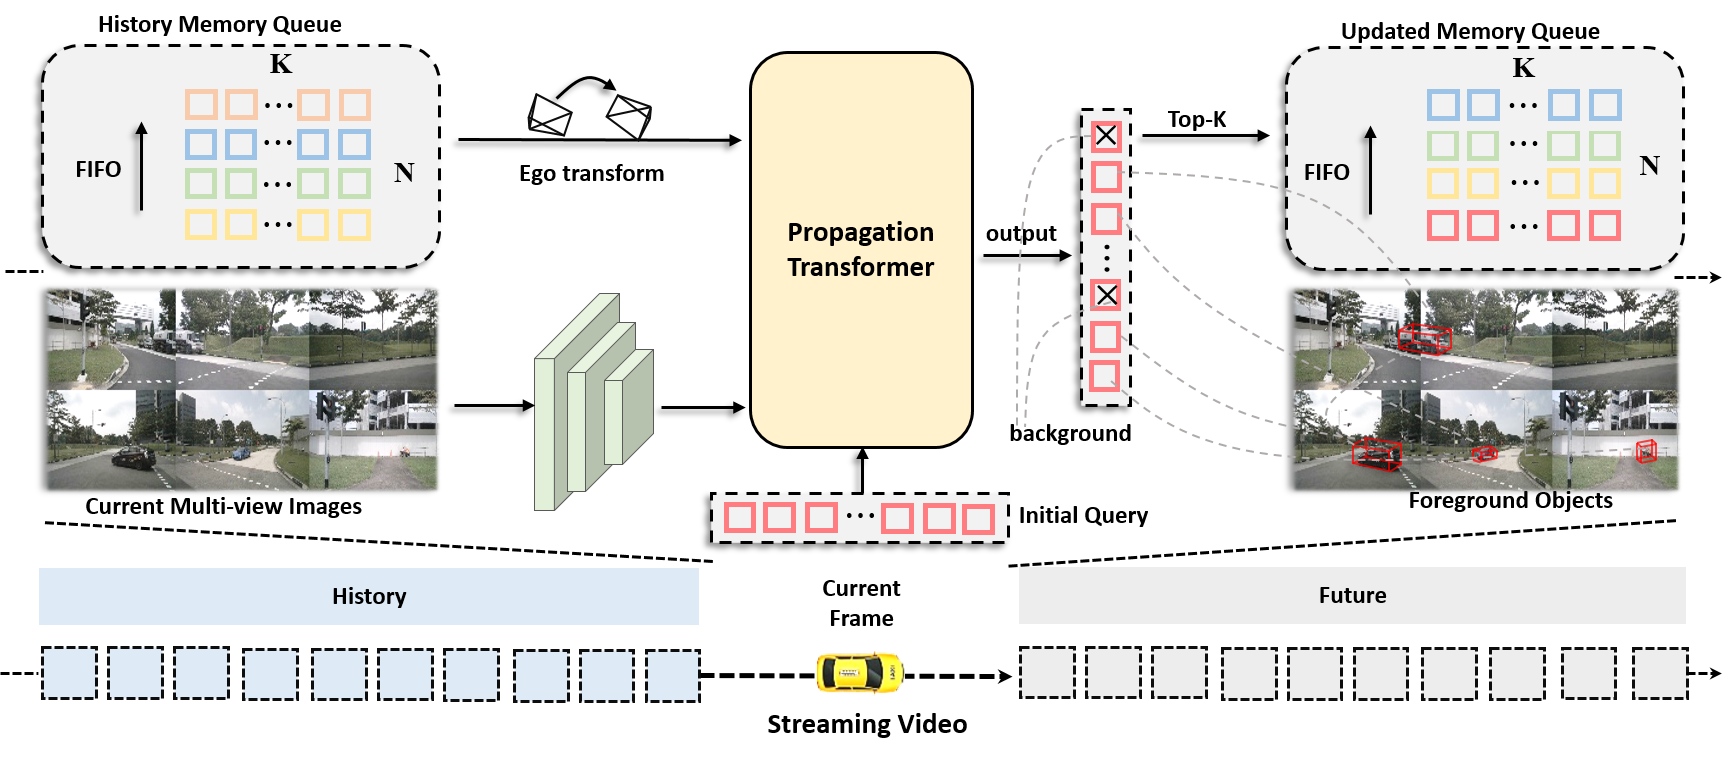
StreamPETR: Object-Centric Temporal Modeling for Multi-View 3D Detection
800+ GitHub stars; followed by Sparse4Dv2/v3, StreamMapNet, and DriveTransformer. Integrated into Autoware as its first camera-only 3D detection node, and released by NVIDIA as a TensorRT reference for DRIVE Orin.
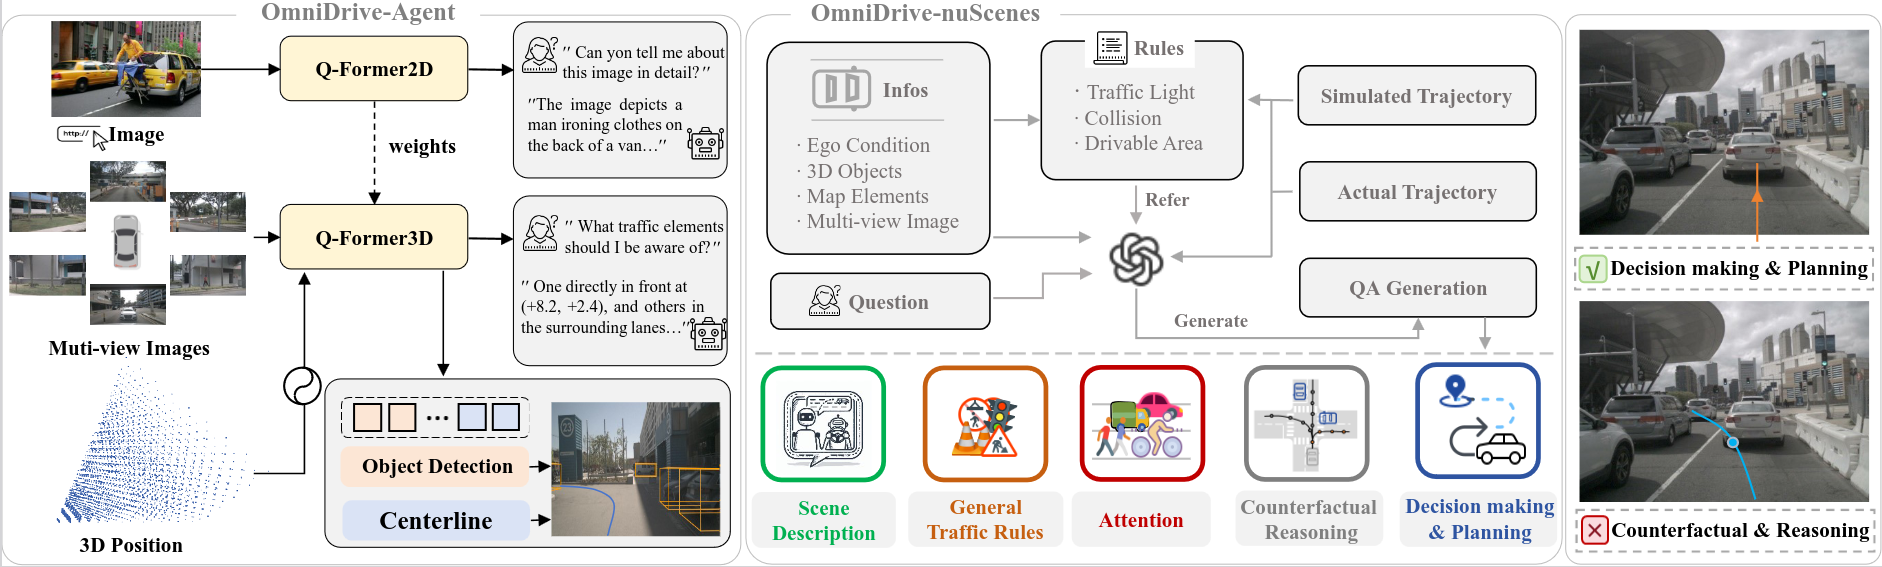
OmniDrive: A Holistic Vision-Language Dataset for Autonomous Driving with Counterfactual Reasoning
A 3D-grounded driving VLM with a counterfactual “what-if” data pipeline. NVlabs released TensorRT-LLM / Edge-LLM deployments on DRIVE AGX Thor; a foundation for the DriveLM Challenge.
Inside NVIDIA foundation models
Publications
* Equal contribution. Full list on Google Scholar.
Conference & Journal Papers
- Shihao Wang, Shilong Liu, Yuanguo Kuang, Xinyu Wei, Yangzhou Liu, Zhiqi Li, Yunze Man, Guo Chen, Andrew Tao, Guilin Liu, Jan Kautz, Lei Zhang, Zhiding Yu. LocateAnything: Fast and High-Quality Vision-Language Grounding with Parallel Box Decoding. ECCV 2026 HF #1 Paper of the Day
- Pengfei Wang, Shihao Wang, Liyi Chen, Zhiyuan Ma, Guowen Zhang, Lei Zhang. DepthMaster: Unified Monocular Depth Estimation for Perspective and Panoramic Images. NeurIPS 2026
- Shihao Wang, Guo Chen, De-An Huang, Zhiqi Li, Minghan Li, Guilin Liu, Jan Kautz, Jose M. Alvarez, Lei Zhang, Zhiding Yu. VideoITG: Multimodal Video Understanding with Instructed Temporal Grounding. CVPR 2026 Highlight
- Tianyi Xiong*, Shihao Wang*, Guilin Liu, Yi Dong, Ming Li, Heng Huang, Jan Kautz, Zhiding Yu. PhyCritic: Multimodal Critic Models for Physical AI. CVPR 2026
- Yunze Man, Shihao Wang, Guowen Zhang, Johan Bjorck, Zhiqi Li, Liang-Yan Gui, Jim Fan, Jan Kautz, Yu-Xiong Wang, Zhiding Yu. LocateAnything3D: Vision-Language 3D Detection with Chain-of-Sight. CVPR 2026
- Rongyuan Wu, Lingchen Sun, Zhengqiang Zhang, Xiangtao Kong, Jixin Zhao, Shihao Wang, Lei Zhang. VOSR: A Vision-Only Generative Model for Image Super-Resolution. CVPR 2026
- Guo Chen, Zhiqi Li, Shihao Wang, Jindong Jiang, Yicheng Liu, Lidong Lu, De-An Huang, Wonmin Byeon, Matthieu Le, Tuomas Rintamaki, et al. Eagle 2.5: Boosting Long-Context Post-Training for Frontier Vision-Language Models. NeurIPS 2025
- Rongyuan Wu, Lingchen Sun, Zhengqiang Zhang, Shihao Wang, et al. DP2O-SR: Direct Perceptual Preference Optimization for Real-World Image Super-Resolution. NeurIPS 2025
- Shihao Wang, Zhiding Yu, Xiaohui Jiang, Shiyi Lan, Min Shi, Nadine Chang, Jan Kautz, Ying Li, Jose M. Alvarez. OmniDrive: A Holistic Vision-Language Dataset for Autonomous Driving with Counterfactual Reasoning. CVPR 2025
- Min Shi, Fuxiao Liu, Shihao Wang, Shijia Liao, Subhashree Radhakrishnan, Yilin Zhao, De-An Huang, Hongxu Yin, Karan Sapra, Yaser Yacoob, et al. Eagle: Exploring the Design Space for Multimodal LLMs with Mixture of Encoders. ICLR 2025
- Zhenxin Li, Shihao Wang, Shiyi Lan, Zhiding Yu, Zuxuan Wu, Jose M. Alvarez. Hydra-NeXt: Robust Closed-Loop Driving with Open-Loop Training. ICCV 2025
- Yuhui Wu, Liyi Chen, Ruibin Li, Shihao Wang, Chenxi Xie, Lei Zhang. InsViE-1M: Effective Instruction-based Video Editing with Elaborate Dataset Construction. ICCV 2025
- Xiaohui Jiang, Shuailin Li, Yingfei Liu, Shihao Wang, Fan Jia, Tiancai Wang, Lijin Han, Xiangyu Zhang. Far3D: Expanding the Horizon for Surround-View 3D Object Detection. AAAI 2024
- Shihao Wang, Yingfei Liu, Tiancai Wang, Ying Li, Xiangyu Zhang. Exploring Object-Centric Temporal Modeling for Efficient Multi-View 3D Object Detection (StreamPETR). ICCV 2023 630+ citations
- Shihao Wang, Xiaohui Jiang, Ying Li. Focal-PETR: Embracing Foreground for Efficient Multi-Camera 3D Object Detection. IEEE T-IV 2023
Preprints & Technical Reports
- Xuyang Liu, Shihao Wang, Xinyu Wei, Minghan Li, Zeqing Wang, Zuhao Yang, Zichen Wen, Lei Zhang. OmniCompass: A Holistic Benchmark for Omni-Modal Video Grounding and Understanding. arXiv 2026
- NVIDIA Nemotron Team. Nemotron 3.5 Super and Lightning. Technical Report 2026
- Johan Bjorck, Zhiqi Li, Yunze Man, Jing Wang, An-Chieh Cheng, Sifei Liu, Shihao Wang, Zhiding Yu, et al. Vesta: A Generalist Embodied Reasoning Model. arXiv 2026
- NVIDIA Cosmos Team. Cosmos 3: Omnimodal World Models for Physical AI. arXiv 2026 (Contributor: Reasoner post-training data for 2D grounding and robotics; reasoning benchmarks.)
- NVIDIA Nemotron Team. Nemotron 3 Nano Omni: Efficient and Open Multimodal Intelligence. arXiv 2026
- NVIDIA GEAR Team. GR00T N1.5 / N1.6: Open Foundation Models for Generalist Humanoid Robots. NVIDIA Research 2025
- Zhiqi Li, Guo Chen, Shilong Liu, Shihao Wang, Vibashan VS, Yishen Ji, Shiyi Lan, Hao Zhang, Yilin Zhao, Subhashree Radhakrishnan, et al. Eagle 2: Building Post-Training Data Strategies from Scratch for Frontier Vision-Language Models. arXiv 2025
- Min Shi, Shihao Wang, Chieh-Yun Chen, Jitesh Jain, Kai Wang, Junjun Xiong, Guilin Liu, Zhiding Yu, Humphrey Shi. Slow-Fast Architecture for Video Multi-Modal Large Language Models. arXiv 2025
- Yuqian Yuan, Wenqiao Zhang, Xiangtai Li, Shihao Wang, et al. PixelRefer: A Unified Framework for Spatio-Temporal Object Referring with Arbitrary Granularity. arXiv 2025
- Jihao Liu, Zhiding Yu, Shiyi Lan, Shihao Wang, Rongyao Fang, Jan Kautz, Hongsheng Li, Jose M. Alvarez. StreamChat: Chatting with Streaming Video. arXiv 2024
- Zhenxin Li, Kailin Li, Shihao Wang, Shiyi Lan, Zhiding Yu, Yishen Ji, Zhiqi Li, Ziyue Zhu, Jan Kautz, Zuxuan Wu, et al. Hydra-MDP: End-to-End Multimodal Planning with Multi-Target Hydra-Distillation. arXiv 2024 (Winner, CVPR 2024 End-to-End Driving at Scale Challenge.)
Research Experience
- Conceived and led LocateAnything (ECCV 2026) and proposed Parallel Box Decoding, which uses diffusion language modeling and multi-token prediction to decode each box/point as a single unit, with a hybrid fallback to autoregressive decoding.
- Built the large-scale training/inference infrastructure and led LocateAnything-Data (12M images, 138M queries) across four domains.
- Principal contributor to LocateAnything3D (CVPR 2026).
- Contributor to Cosmos 3: Reasoner post-training data for 2D grounding and robotics, and the reasoning results and benchmarks used to evaluate the Reasoner tower.
- Co-first author of PhyCritic (CVPR 2026), multimodal critic models for Physical AI.
- Isaac GR00T N1.6: vision-language base model on Eagle 2.5 with native any-resolution input, and the large-scale spatial-understanding data.
- Vesta: led the data engine for perception and spatial understanding.
- Nemotron 3 Nano Omni: visual grounding and GUI-understanding capabilities.
- Helped design and scale the Eagle VLM family (Eagle, Eagle 2, Eagle 2.5), building post-training data strategies and long-context recipes from scratch.
- Developed VideoITG (CVPR 2026 Highlight) with the VidThinker agentic annotation workflow.
- Core contributor to the vision-language (System-2) foundation of GR00T N1.5.
- Developed OmniDrive (CVPR 2025) with a counterfactual “what-if” data pipeline that supervises why alternative trajectories fail.
- Proposed the core ideas of Hydra-MDP: a vocabulary of trajectory anchors scored by multiple judge heads distilled from rule-based teachers; contributed to Hydra-NeXt (ICCV 2025).
- Developed StreamPETR (ICCV 2023): outperformed BEVFormer at ~10% of its training cost, the first camera-only 3D detector to match LiDAR performance on nuScenes.
- Contributed to Far3D (AAAI 2024) for long-range (up to 150 m) surround-view detection.
Honors & Awards
- Hugging Face #1 Paper of the Day, LocateAnything2026
- Highlight Paper, CVPR 2026: VideoITG2026
- Winner (1st of 143 teams) & Innovation Award, CVPR 2024 Challenge on End-to-End Driving at Scale2024
- 2nd Place, CVPR 2024 Challenge on Driving with Language2024
- 1st Place, nuScenes leaderboard on camera-only 3D multi-object tracking2023
Education
Invited Talks
- OmniDrive: Advancing autonomous driving 3D perception, reasoning, and planning with large models2024.07
- Sparse vectorized representation for long-term temporal modeling2023.12
- How can BEV perception be achieved without BEV features?2023.08
Academic Services
- Conference Reviewer: CVPR, ICCV, ECCV, NeurIPS, ICML, ICLR
- Journal Reviewer: IEEE Transactions on Pattern Analysis and Machine Intelligence (T-PAMI)
- Workshop Organizer: OpenReview Workshop2026
© Shihao Wang · Paper figures are from the respective publications. Hero photos via Wikimedia Commons: Freedom Gundam statue by Conniecc120121 (CC BY 4.0); Unicorn Gundam statue (CC0).

